Open-weight typed decisions, running natively on Apple Silicon.
13.4 ms median end-to-end for a short English typed decision. 7.4 ms with the multilingual checkpoint. 0 output tokens. Local MLX inference, with no PyTorch, Transformers runtime, or cloud API.
中文 · Benchmarks · Snake demo · Hugging Face weights
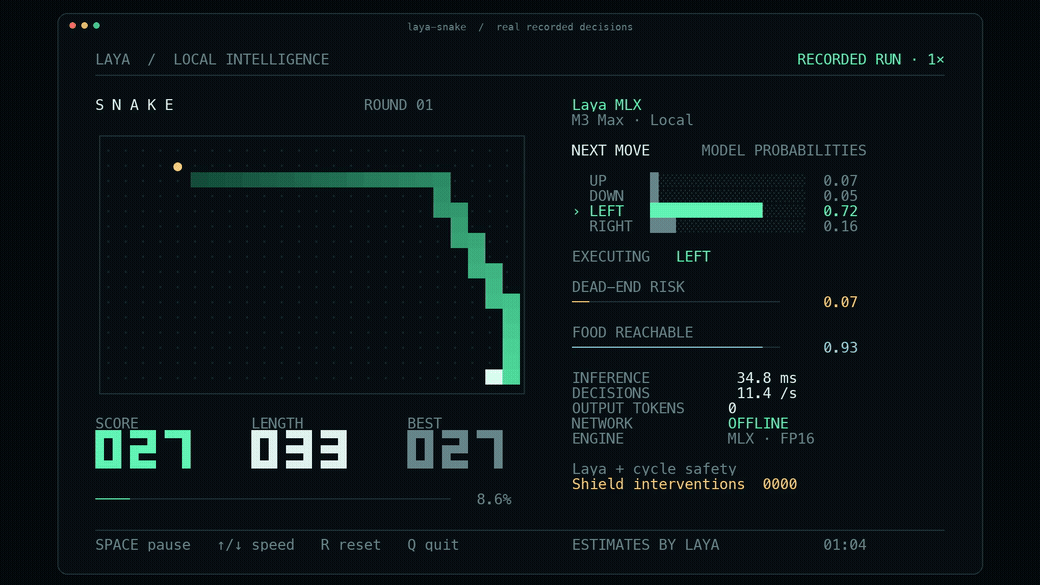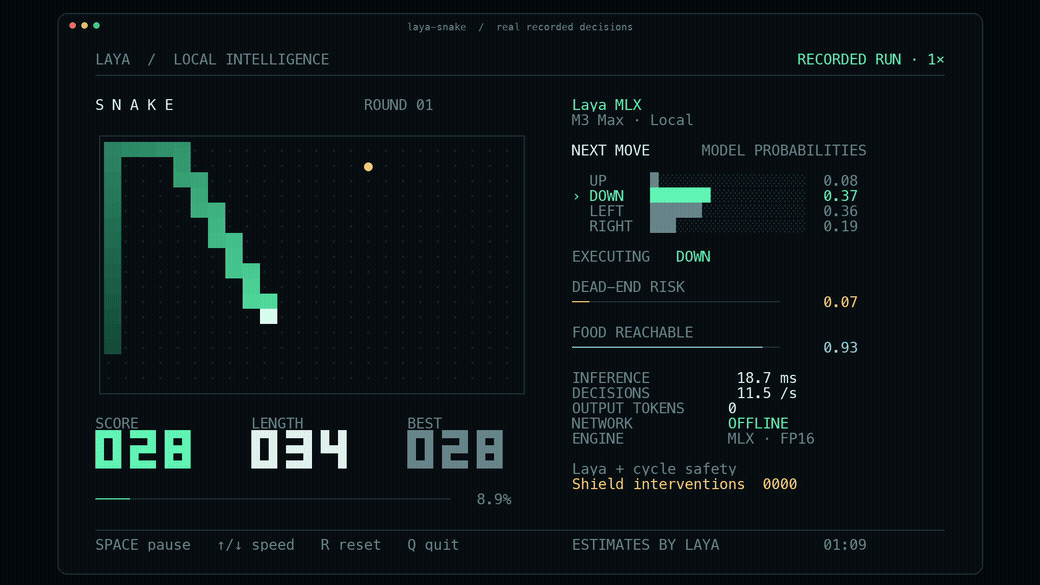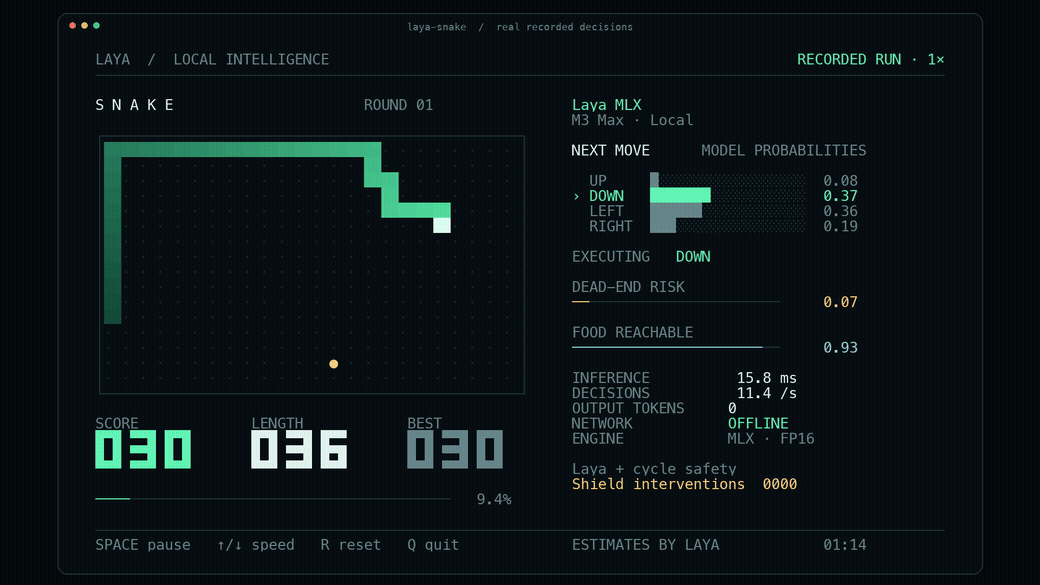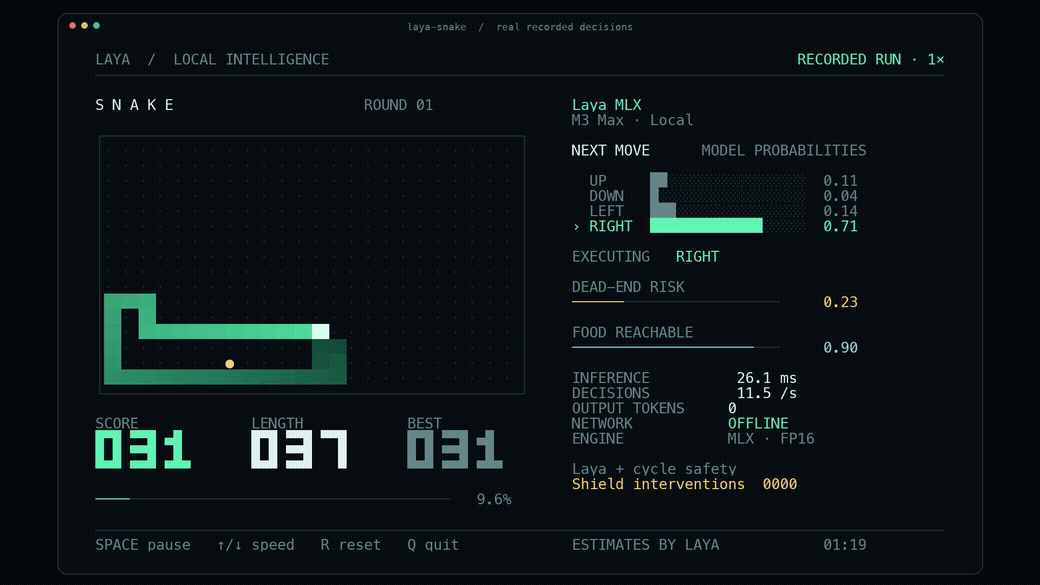
The GIF is an original-speed render of a real local Snake run. Every move calls Laya; the visible cycle safety layer can correct unsafe proposals. The latency figures above are the separate one-question API benchmark, not the frame time of the three-question Snake loop. Watch the 30-second MP4 · Snake speed and stability.
pip install laya-mlximport laya_mlx as laya
agent = laya.load("aac6fef/laya-mlx")
result = agent.predict(
"I was billed twice. Please refund the duplicate.",
{
"department": {
"type": "choice",
"instructions": "Who should handle this?",
"criteria": ["billing", "technical", "sales"],
}
},
)
print(result["answers"]["department"])Apple Silicon, Python 3.11+, macOS 14+. First load downloads the checkpoint; later inference is fully local. The measured environment is macOS 27.2, Python 3.12.13 and MLX 0.32.2. That MLX release supplies macOS 14, 15 and 26 wheels; the local installer selected the 26 wheel. Older supported macOS versions were not tested on this machine.
Run the terminal demo:
pip install 'laya-mlx[demo]'
hf download aac6fef/laya-multilingual-mlx
laya-snake
Download once before the offline demo. Use a terminal at least 104 × 35 cells. Space pauses, ↑/↓ changes speed, R resets and Q quits. laya-snake --max-speed makes a fresh decision for every move without pacing. Recording, controls and exact metric meanings.
laya-snake --optimize --max-speed enables the tested compilation and prefix-reuse path: 75.40 moves/s across 2,400 moves, zero deaths and 2 visible safety interventions in the paired M3 Max test. This was about 6.5% faster than its same-run eager control. Gameplay, performance and correctness evidence.
| FP16, end-to-end | Laya 421M | Multilingual 322M |
|---|---|---|
| One short question, P50 | 13.42 ms | 7.39 ms |
| One short question, P95 | 13.92 ms | 7.79 ms |
| 50-question throughput | 146.8 q/s | 395.0 q/s |
| Peak MLX allocation, one short question | 943.6 MiB | 687.6 MiB |
M3 Max, 40 GPU cores, 128 GiB memory. Timing includes prompt preparation, tokenization, tensors, synchronized inference, calibration and result formatting; model loading is excluded. The 50-question measurement uses batch_size=64; the API defaults to 16. Different lengths, question counts and runtime conditions change latency. Full method and every timing sample.
Port fidelity: all three checkpoints matched the upstream selected answer on 63/63 validation questions in both FP32 and FP16 — 378/378 comparisons. Each configuration also passed 100 repeated finite, deterministic calls with zero measured active-memory growth. This measures fidelity on those fixtures, not accuracy on every possible question. Probability errors and validation.
Software often needs a choice, a rubric score or a probability. Laya answers those constrained questions in a bidirectional forward pass, without token-by-token decoding or generated JSON.
state + typed question → bidirectional encoder → decision heads → probabilities
choice: probabilities over named options.score: probabilities over ordered rubric levels and their expected score.noul: P(true) for a proposition.
Question rows are batched independently. Their bidirectional encoder representations depend on both state and question; this runtime does not claim to encode the state once and reuse its hidden states across arbitrary questions.
The encoder, decision Transformer, scoring head and action head all run in MLX. Tokenization uses Hugging Face's Rust tokenizer. The original pretrained weights, question formatting, calibration and output schema are retained. This is an independent MLX port, not an official Convai Innovations release.
| Model | Encoder | Parameters | Context limit | Purpose |
|---|---|---|---|---|
convaiinnovations/laya |
ModernBERT-large | 421M | 512 | English |
convaiinnovations/laya-multilingual |
mmBERT-base | 322M | 1,024 | Multilingual input |
convaiinnovations/laya-typed-decisions |
ModernBERT-large | 421M | 1,024 | Upstream typed-decisions workflows |
Context includes instructions, options and state. All three use the original weights, prompt formatting, temperature calibration, and output schema. This repository provides inference and conversion; RLCD training and fine-tuning remain in the upstream project. It is an independent port, not an official Convai Innovations release.
Pre-converted FP16 checkpoints are published on Hugging Face:
Load these directly with laya.load("aac6fef/laya-mlx"), or use the original checkpoint IDs above. Each published checkpoint includes its model card, validation results, provenance, license and file checksums. All 36 published files passed strict remote checksum verification; pinned revisions and weight hashes are recorded in hub-publication.json.
gh repo clone mizorewww/laya-mlx
cd laya-mlx
uv sync --extra demo
uv run --extra demo laya-snake
Or install the latest GitHub revision with pip install 'git+https://github.com/mizorewww/laya-mlx.git'. Model weights are downloaded separately and are excluded from Git.
import laya_mlx as laya

agent = laya.load("aac6fef/laya-mlx", dtype="float16")
result = agent.predict(
    "I was billed twice. Please refund the duplicate today.",
    {
        "department": {
            "type": "choice",
            "instructions": "Which team should handle this request?",
            "criteria": {
                "billing": "invoices, payments, refunds",
                "technical": "bugs and outages",
                "sales": "new purchases",
            },
        },
        "urgency": {
            "type": "score",
            "instructions": "How urgent is this request?",
            "criteria": ["not urgent", "soon", "critical"],
        },
        "refund": {
            "type": "noul",
            "instructions": "Does the customer ask for money back?",
        },
    },
)
print(result["answers"])
system_one is an alias for predict. States can be text, JSON dictionaries, or conversation lists. choice accepts a dictionary or a list of unique labels; score returns the expected zero-based rubric level; noul returns P(true). Results retain upstream's four-decimal rounding, action.act_probability, and token usage fields.
The default precision is FP16. Use dtype="float32" for closer numerical agreement. Probabilities can differ slightly across precisions even when the selected label agrees; see the measured errors in BENCHMARKS.md. BF16 can be requested but is not part of the published validation matrix.
Following upstream v0.3.5, fitted calibration temperatures are clamped to [0.5, 5.0] before use: the shipped choice:11+ bucket is 0.1006, which would sharpen logits ~10x and report a coin flip as near-certainty. The checkpoint's raw values remain available as agent.temperature_raw and agent.temperature_by_options_raw, and a RuntimeWarning names every clamped bucket at load.
batch_size=16 caps the number of questions per forward pass; larger requests are processed in chunks. Increase it when memory allows. device="gpu" or device="cpu" selects a device explicitly; otherwise MLX's default device is used.
For repeated workloads, opt into compile=True, pad_to_multiple=16 and cache_prompts=True when loading an Agent. The prefix cache is bounded to 128 questions and shares CPU state tokenization, while every question still gets its own encoder computation. Compilation has a first-use cost and shape specialization; padding may make some workloads slower. All three options default to disabled. Measured Snake ablation and usage.
agent = laya.load("./models/laya", dtype="float32", batch_size=32)
# Select one checkpoint inside upstream's bundled repository:
multi = laya.load("convaiinnovations/laya", subfolder="multilingual")
# Pin a Hub revision for reproducibility:
agent = laya.load(
    "convaiinnovations/laya",
    revision="c5d78730f3493e4fe16d61507ef4b78eef7318cf",
)
Loading validates every parameter name and shape. Unsupported encoders and non-default RoPE scaling fail explicitly. ModernBERT's global/local attention pattern, inclusive sliding-window boundary, distinct local/global RoPE bases, and first-layer normalization behavior are preserved.
from laya_mlx import Router, triage_questions

router = Router(dtype="float16", max_loaded=2)
result = router.predict({"message": "发票被重复扣款,请退款。"}, triage_questions())
print(result["routing"])  # multilingual

# Choose the specialized checkpoint explicitly:
result = router.predict(state, questions, task="typed_decisions")
The router, language heuristics, email helpers and application presets are adapted from upstream. Router(preload=True) keeps all three checkpoints resident; attach, preload, unload, explicit lang=, and explicit model= are supported. Model lifecycle is guarded by a re-entrant lock, so concurrent threads share one loaded Agent instead of building duplicates; inference itself is not serialized. Typed-decisions workflow detection stays opt-in. The port preserves model limitations: English checkpoints are not substitutes for the multilingual checkpoint, and confidence does not guarantee accuracy.
Unidentified Latin-script languages (Romanian, Polish, Czech, Turkish, ...) route to the multilingual checkpoint on their non-English letters alone, rather than being silently assumed English. detect_language(state) reports the evidence: language_undecided and diacritic_rate alongside language and is_english.
Choice options share one head_max_len token budget, so a question with hundreds of labels leaves only a few tokens per label. predict_shortlist embeds the state and each label, keeps the top k by cosine similarity, and runs a single predict on the reduced set. This is opt-in: Agent.predict still scores every criterion it is given.
import laya_mlx as laya

agent = laya.load("aac6fef/laya-mlx")
embed_fn = laya.embed_fn_from_agent(agent)  # mean-pools the loaded encoder; no extra weights
result = laya.predict_shortlist(agent, state, questions, embed_fn, k=20)
print(result["shortlist"])  # which labels were kept, with cosine scores
A dedicated bi-encoder passed as embed_fn usually shortlists better than the decision checkpoint's own encoder. Probabilities on a shortlisted choice are over the kept labels only.
uv run laya-mlx predict \
  --model aac6fef/laya-mlx \
  --state-file examples/state.json \
  --questions examples/questions.json

uv run laya-mlx predict \
  --model aac6fef/laya-multilingual-mlx \
  --state '发票被重复扣款,请退款。' \
--questions examples/questions.jsonVersion 0.4.0 selectively incorporates upstream 1adc59f
(v0.4.1). Behavior change: Router() now defaults to multilingual for undecided
text, including very short inputs such as "refund me". Identified English still routes
to english; use Router(default="english") to retain the previous fallback. The default
resident cap remains one; use max_loaded=2 or preload when alternating languages.
Cold checkpoint construction runs outside the lifecycle lock. Concurrent loads of the same
checkpoint share a build; resident loads and status reads remain available. unload(name)
waits only for that checkpoint's build, while unload() waits for all builds. Eviction and
unload release the MLX free-buffer cache; references held by a caller or an in-flight prediction
remain valid. Cache clearing is process-wide and may cause later buffer allocations.
Custom checkpoints can be registered alongside the built-ins without loading immediately:
from laya_mlx import Router, predict_tournament

router = Router(models={"billing": "./models/billing-mlx"})
router.register("support", "./models/support-mlx", description="Support classifier")
result = router.predict(state, questions, model="support")
print(router.registered)
router.unregister("support")
Names are case-normalized and may contain letters, digits, ., _, and -; built-in aliases
retain their meaning. Replacing a source invalidates the old resident model and prevents an old
in-flight build from entering the cache. attach("custom", agent) also registers a name, but a
source must be registered before reloading it after unload. Built-ins and the current default
cannot be unregistered. Use register for changes rather than mutating router.models directly.
Agent.predict and Router.predict accept an optional scalar or per-option-count confidence gate:
result = agent.predict(
    state,
    questions,
    min_confidence={
        "choice:2": 0.8,
        "choice:11+": 0.95,
        "default": 0.7,
    },
)
for answer in result["answers"].values():
    if answer["abstention"] != "passed":
        print("Needs review", answer)
The gate adds abstention (passed, abstained, or unevaluated),
abstention_threshold, and low_confidence=True for answers below the threshold. It preserves
the answer and does not invoke a fallback automatically. Missing bucket thresholds fall back to
default, then zero. Bucket sizes are 2, 3-5, 6-10, and 11+, prefixed by choice:,
score:, or noul:. Invalid names and non-finite thresholds fail before inference. Without
min_confidence, these fields are absent. The gate uses answer_confidence (the maximum option
probability); temperature clamping alone does not make it a calibrated probability of correctness.
For large choice sets, predict_tournament needs no embedding model:
result = predict_tournament(router, state, questions, group_size=16, model="billing")Each round chooses one winner per group and continues until at most group_size finalists
remain. This costs additional inference passes and can lose a good candidate in an early round;
grouping follows criteria order. The final probabilities, confidence, and usage describe only
the final pass, not all original options or total computation. tournament[qid] reports finalist
labels, original label count n, and elimination rounds. Small choices and non-choice questions
pass through to the final call unchanged.
Checkpoints trained with "option_layout": "parallel" are supported end to end: shared option
positions, option-isolating attention masks, MLX inference (including compile=True), prefix
caching, and conversion. Missing configuration means sequential, preserving existing published
checkpoints; unknown layouts raise an error. Do not enable parallel layout by editing an old
checkpoint's config: its weights were trained with a different input layout. Permutation
invariance is verified within floating-point tolerances on tiny random models; this is not a
task-accuracy claim for new weights. Compiled/FP16 reductions can differ in the last decimals,
and exact or near ties can choose a different label. CPU parallel-layout inference uses FP32
intermediate math to avoid native half-precision kernel failures on hosted macOS 26; parameter
storage precision is preserved, and GPU execution retains the requested precision.
Language detection now avoids treating all-capital acronyms/address fragments as French or
Spanish while preserving emphasis capitals and mixed scripts. French device footers such as
Envoyé depuis mon iPhone are correctly removed. Language detection remains heuristic.
The original sequential architecture checks remain pinned to 573e5b6; parallel layout checks
use the actual upstream v0.4.1 implementation pinned at 1adc59f. CI runs both references. The three published checkpoints were rechecked in FP32/FP16:
378/378 argmax agreements, 100 deterministic finite calls per configuration, and zero measured
active-memory growth (raw validation report).
This port does not include the upstream batch/long-document, structured-decisions, hooks,
HTTP/MCP server, training, or other backend/SDK APIs.
The runtime selectively incorporates input, routing and email fixes from upstream
4aa6761 (v0.3.23 source tree). This does not add the upstream batch, long-document,
hooks or server APIs. Neural architecture parity remains tested against 573e5b6.
- Chronological conversation lists keep their newest tokens when the context fills; strings and dictionaries keep their beginning. Prefix caching uses the same rule.
noulcriteria accept onlyfalse/truekeys (including Python boolean keys). Optionallabels={"false": "no", "true": "yes"}changes the words shown to the model while the answer remains P(true). Invalid keys now raise instead of being ignored.- Non-string instructions preserve Unicode. Empty instructions, null score levels,
and a
Nonestate raise a caller error; question errors name the question. - Every answer adds
answer_confidence, the maximum calibrated option probability. Existingconfidenceretains its entropy-based meaning for choice/score and maximum probability for noul. Neither field guarantees accuracy on a new task. usageaddsstate_tokens,state_tokens_dropped(the largest drop across questions),truncated, andtruncated_questions.usage.optionsappears only for questions whose option token spans collide, reportingtotal,distinct, andtokens_per_option. This reports lost distinctions; it does not recover them or remove position bias.- Incremental
Router.preload()preserves resident models;preload([])does nothing. Blank or language-neutral hints fall through to detection, and undecided Latin text respectsRouter(default=...). Detection examines nested string values and mixed text. - Email cleaning preserves ordinary requests mentioning confidentiality, thanking the
recipient, or starting with
From:while recognizing multilingual mail footers.
uv run laya-mlx convert \
  --model convaiinnovations/laya \
  --dtype float16 \
  --output models/laya-mlx-fp16

uv run laya-mlx predict \
  --model models/laya-mlx-fp16 \
  --state-file examples/state.json \
  --questions examples/questions.json
The export contains model.safetensors, encoder and agent configurations, tokenizer files and mlx_config.json. Existing output directories are never overwritten. This is a parameter-name/dtype conversion, not quantization or retraining. The source checkpoints already store FP16 weights; choosing FP32 increases arithmetic precision, not the precision of the source weights.
uv sync --extra dev --extra reference --extra benchmark --extra demo
source .venv/bin/activate
gh repo clone NandhaKishorM/laya .upstream
git -C .upstream checkout 573e5b62696ba441230cd6be71d593331b5d23af
# Independent reference for parallel-layout parity:
gh repo clone NandhaKishorM/laya .cache/upstream-v0.4.1
git -C .cache/upstream-v0.4.1 checkout 1adc59f7e371deb601fcfa18a14e25db238addcc
pytest -q
python -m benchmarks.download
python -m benchmarks.validate --repeats 100
python -m benchmarks.run --iterations 50 --warmup 5
python -m benchmarks.accuracy --per-class 64
python -m benchmarks.report
Run GPU measurements sequentially. Unit tests use small random models and include direct comparisons with Transformers and the pinned upstream decision head. Real checkpoint validation tests tokenization, logits, calibrated probabilities, repeated outputs and active memory growth. The benchmark runs each backend/checkpoint in a fresh process and stores every timing sample in benchmarks/results. The full report explains the timing boundaries and precision differences.
GitHub Actions runs small-model CPU tests on a macOS arm64 runner. Full checkpoint GPU benchmarks are measured locally and are not part of hosted CI.
The performance investigations include both mathematical analysis and independent local experiments:
- Initial performance research: implementation bottlenecks, MLX kernel dispatch, and a controlled experiment plan.
- Mathematical investigation of a further 10× speedup: arithmetic budgets, conditional bandwidth bounds, real weight spectra, exact reuse, and smaller-model designs.
- Engineering investigation: measured compilation, quantization, final-head selection, custom Metal kernels, and representative matrix multiplications.
experiments/ contains the research scripts and their raw measurements. The published runtime's performance and validation results are in BENCHMARKS.md; each experimental variant has its own timing and correctness results.
The current investigation does not support a further universal 10× speedup with the same checkpoints. Selected cases show approximately 1.03–1.08× paired median speedups; the engineering report gives the uncertainty intervals, quantization fidelity results, and custom Metal kernel measurements.
To prepare model cards and verified exports for publication, install the reference extras and run:
python -m scripts.prepare_hub --account YOUR_HF_USERNAME
hf upload YOUR_HF_USERNAME/laya-mlx models/hub/laya-mlx . --exclude '.cache/*'
The preparation script checks every exported tensor against its original FP16 source. Upload the other two prepared folders in the same way, then use hf cache verify REPO_ID --local-dir EXPORT_PATH to check the remote files.
Apache-2.0; see LICENSE and NOTICE. Laya and its pretrained weights are by Convai Innovations and upstream contributors. Prompt construction, output formatting, language routing, email utilities and presets are adapted from NandhaKishorM/laya at commit 573e5b62696ba441230cd6be71d593331b5d23af. The neural architecture is reimplemented in MLX following Laya and Hugging Face ModernBERT.
This project follows upstream Laya's behavior through a native MLX implementation. Upstream-compatible fixes take priority over independent model variants, service APIs, and additional demos. This remains a selective port, not a claim of full upstream API parity.
To release, update the version in pyproject.toml, laya_mlx/__init__.py, and uv.lock,
then push a matching vX.Y.Z tag. GitHub Actions runs the macOS test suite, validates
version consistency, builds and checks the wheel and source distribution, publishes
them to PyPI using the repository's PYPI_API_TOKEN secret, and creates a GitHub release.
A failed test or build prevents publishing.