


Jiamu Zhang1 Tianze Yang1 Yucheng Shi2 Evan Chen1
Zixiang Nie1 Kelly Wan1 Liangjie Hong1 Ninghao Liu3 Liang Wu1
1 Nokia, Sunnyvale, CA, USA 2 Tencent Hunyuan 3 The Hong Kong Polytechnic University
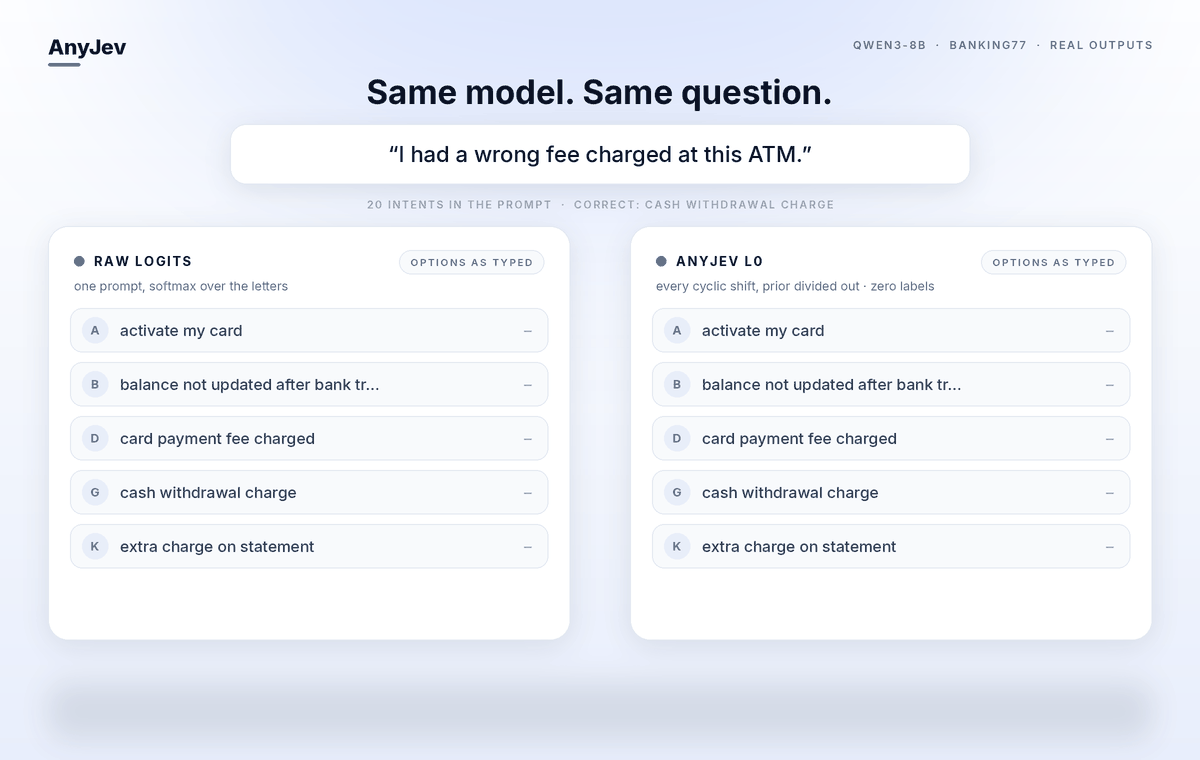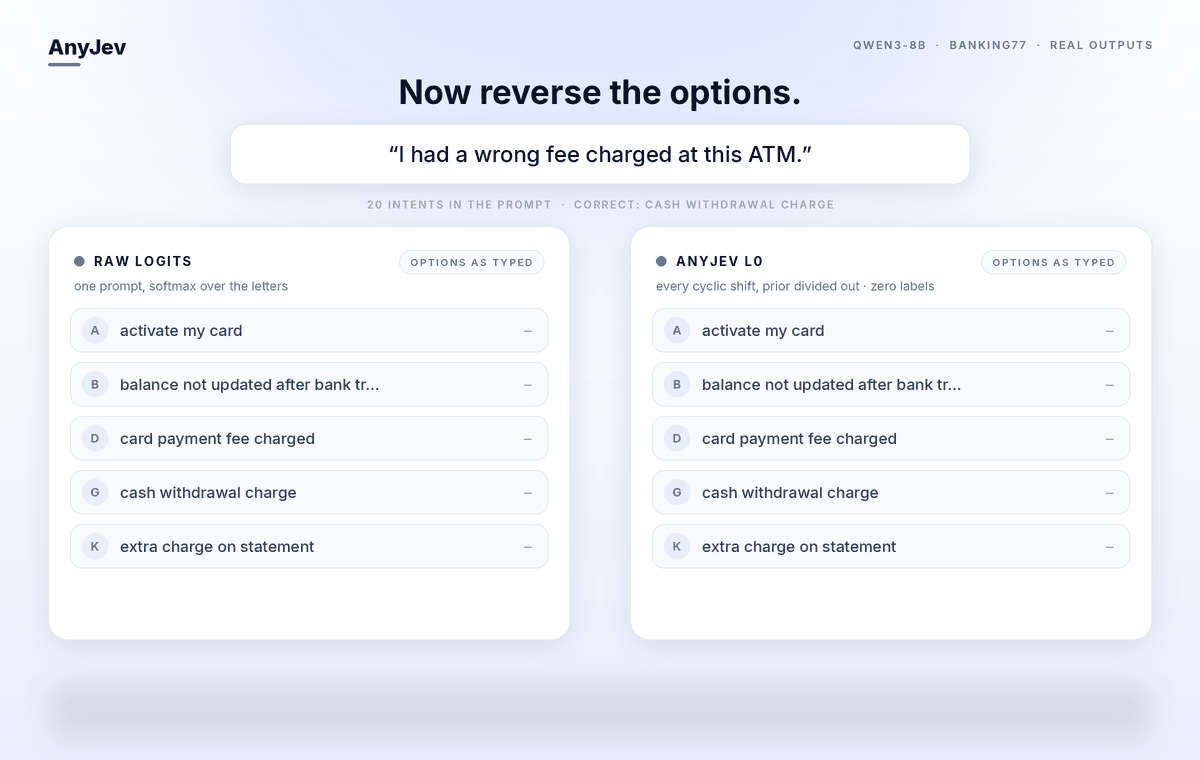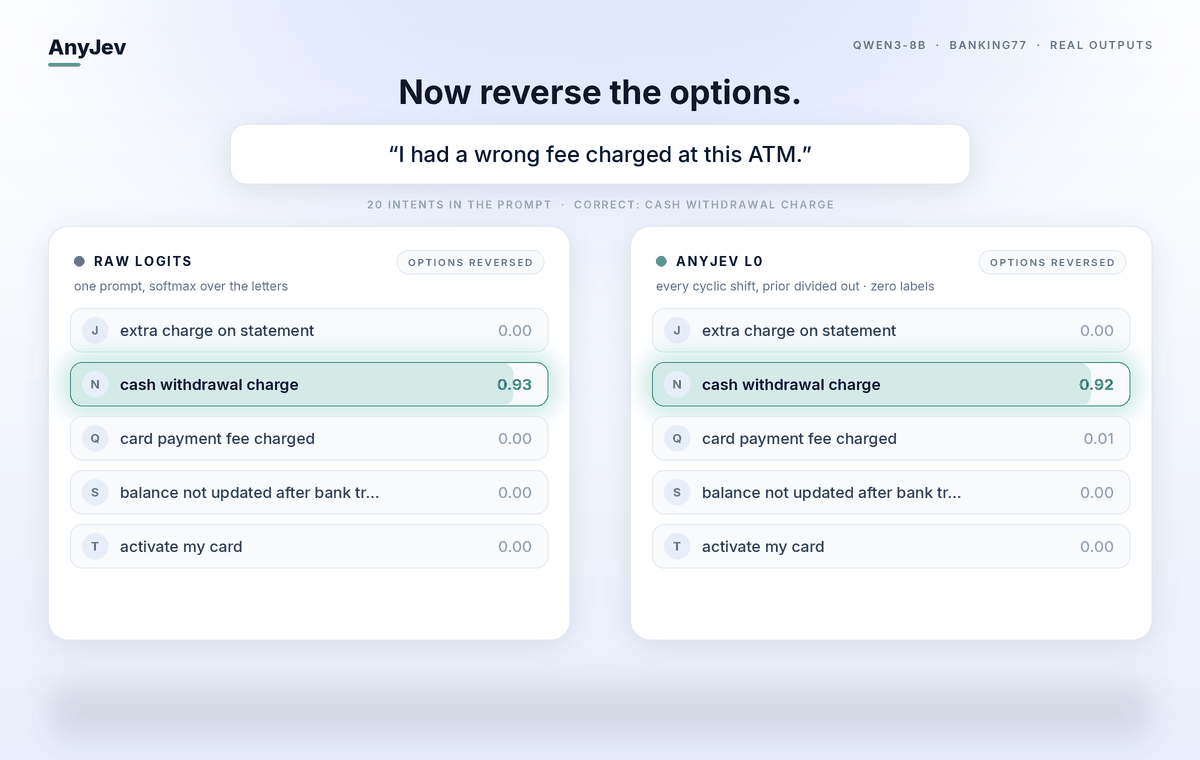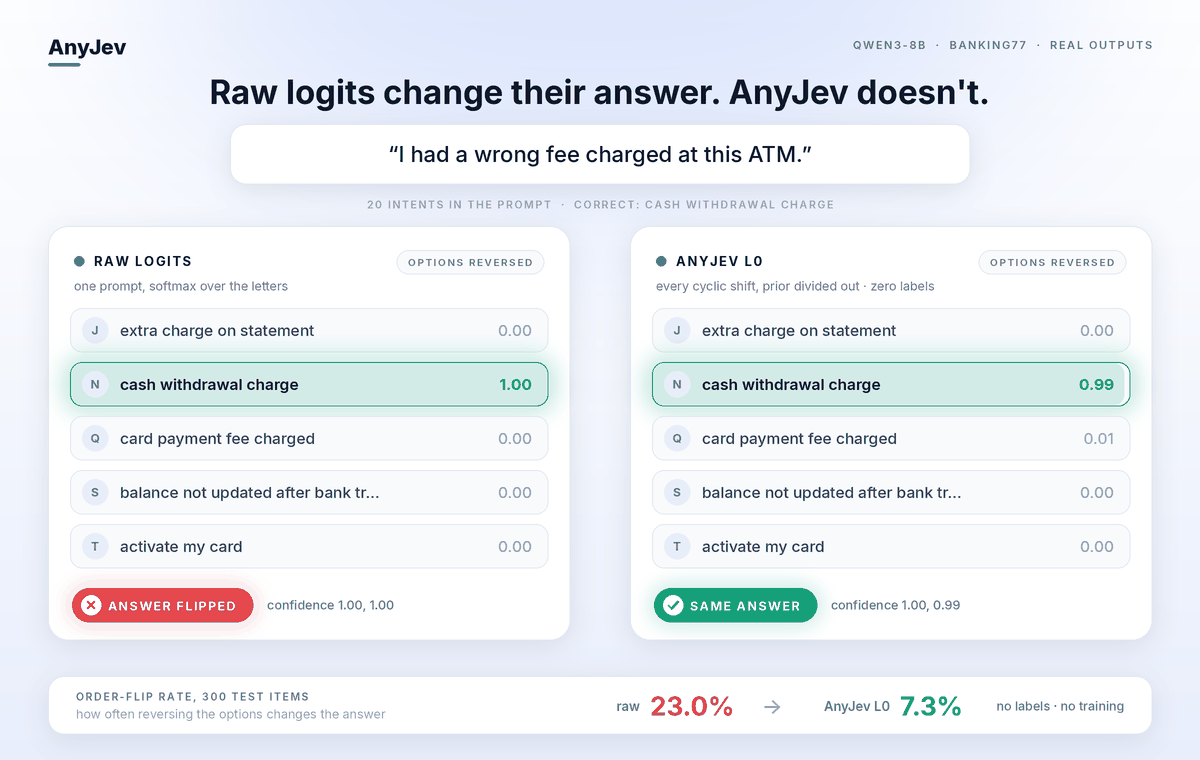
Qwen3-8B on a real BANKING77 item. Every number is a model output.
Tip
🆕 Tacit: AnyJev's self-distilled models, 1.7B to 9B, are on
Hugging Face. One
forward pass per decision. With adaptive=True, a capped share of low-confidence decisions goes to
the model's own reasoning. They run on transformers, in-process vLLM or a stock vllm serve.
pip install "anyjev[hf]", then Tacit.from_pretrained("morriszjm/Tacit-9B").
Start here ↓
Note
🏆 No training, on a public leaderboard. The training-free Decider (L0, two rotations) on the
unchanged Gemma-4-31B has a Full score of 60.22 on the Decision Index 0.3,
5th of 149 entries on 2026-10-12. Details ↓
A Tacit model, in Python.
from anyjev import Tacit

tacit = Tacit.from_pretrained("morriszjm/Tacit-9B")          # transformers, one GPU
d = tacit.decide(state="Customer: my package was due last Monday and it still has not arrived.",
                 question="What does the customer want?",
                 options=["track_order", "cancel_order", "refund", "change_address"])
d["answer"], d["probs"], d["route"]    # an option, {option: probability}, "one_forward" or "cot"
kind is "choice" (default), "yes_no" or "score" (options are ordered levels, lowest
first, numbered from 1; first_level=0 numbers them from 0). decide_batch([...]) takes a list of such dicts.
Send the hardest decisions to reasoning, with a cap.
tacit = Tacit.from_pretrained("morriszjm/Tacit-9B", adaptive=True, tau=0.5, max_cot_share=0.2, cot_window=1000)A decision whose top two options are less than tau apart in log-probability is answered again with
thinking on. After the reasoning, the answer is read as a label distribution, so it also has
probabilities and cannot fail to parse. At most max_cot_share of the last cot_window decisions
escalate, however hard the traffic gets. Every escalation is reported (route == "cot", with the
first pass kept), and tacit.stats counts them.
On vLLM. A stock server; the client needs only the tokenizer.
pip install "anyjev[client]"
vllm serve morriszjm/Tacit-9B --host 127.0.0.1 --port 8000
tacit = Tacit.from_pretrained("morriszjm/Tacit-9B", engine="server",
base_url="http://127.0.0.1:8000", adaptive=True)engine="vllm" (pip install "anyjev[vllm]") runs vLLM in the same process instead.
An HTTP endpoint for many clients sharing one cap.
python -m anyjev.serve --model morriszjm/Tacit-9B --upstream http://127.0.0.1:8000 --adaptive --port 8100
curl -s 127.0.0.1:8100/v1/decide -H 'Content-Type: application/json' \
  -d '{"state": "Customer: my package has not arrived.", "question": "What does the customer want?", "options": ["track_order", "refund"]}'
POST /v1/decide takes one decision or {"items": [...]}; GET /v1/stats reports the escalation
share. The gateway listens on 127.0.0.1 and has no authentication of its own.
| argument | default | meaning |
|---|---|---|
adaptive |
False |
send low-confidence decisions to the model's own reasoning |
tau |
0.5 |
low confidence: the log-probability gap between the top two options is below tau |
max_cot_share |
0.2 |
at most this share of the last cot_window decisions escalates; None removes the cap |
cot_window |
1000 |
how many recent decisions the cap counts; None counts every decision since loading |
cot_max_tokens |
8192 |
reasoning budget of one decision |
engine |
"transformers" |
"vllm" runs vLLM in this process; "server" uses a running vllm serve at base_url |
Any other model, training-free. The Decider reads the same typed decisions from any open
causal LM, with no training and no labels.
from anyjev import Decider, Question
from anyjev.backends.hf import HFBackend          # or VLLMBackend / SGLangBackend(url, model), LlamaCppBackend(gguf)

d = Decider(HFBackend("Qwen/Qwen3-8B"))           # level="L0" by default
route = Question.choice("Which team should handle this?",
                        ["billing", "technical", "sales", "other"], name="route")
r = d.decide("My card was charged twice for one order.", [route])["route"]
r.distribution, r.level                           # {option: probability}, "L0"
L0 reads a K-option choice once per rotation of the options. With the rotation budget, it reads only as many rotations as the decision needs:
d = Decider(backend, adaptive_shifts=True, canonical_order=True)
d.calibrate_adaptive(route, unlabelled_tickets, target=0.01)   # a few hundred states, no labels
The stopping threshold is calibrated against our own full-cycle answer, so it needs no labels. At a certified 1% disagreement it read 7.2 rotations instead of 18. That was 2.2× the decisions per second on vLLM and 2.3×–2.7× on transformers, with accuracy unchanged (docs/rotation_budget.md).
Give the model a state and a typed question (a choice, a yes/no or a score). You get back a decision with a probability over the options, read from the model's next-token distribution. Nothing is parsed. There are two ways in:
- AnyJev Training-Free (
Decider) works on any open LLM, with no training. Raw label logits change their answer when the options are reordered and carry the model's preference for some labels. L0 removes both without a single label. - AnyJev Self-Distilled (
Tacit) uses the Tacit checkpoints. They are trained by self-distillation: the model learns to give, in one forward pass, the answers it reaches when it reasons. No human labels and no other model are involved. One prefill per decision; withadaptive=True, a capped share of decisions goes to reasoning.
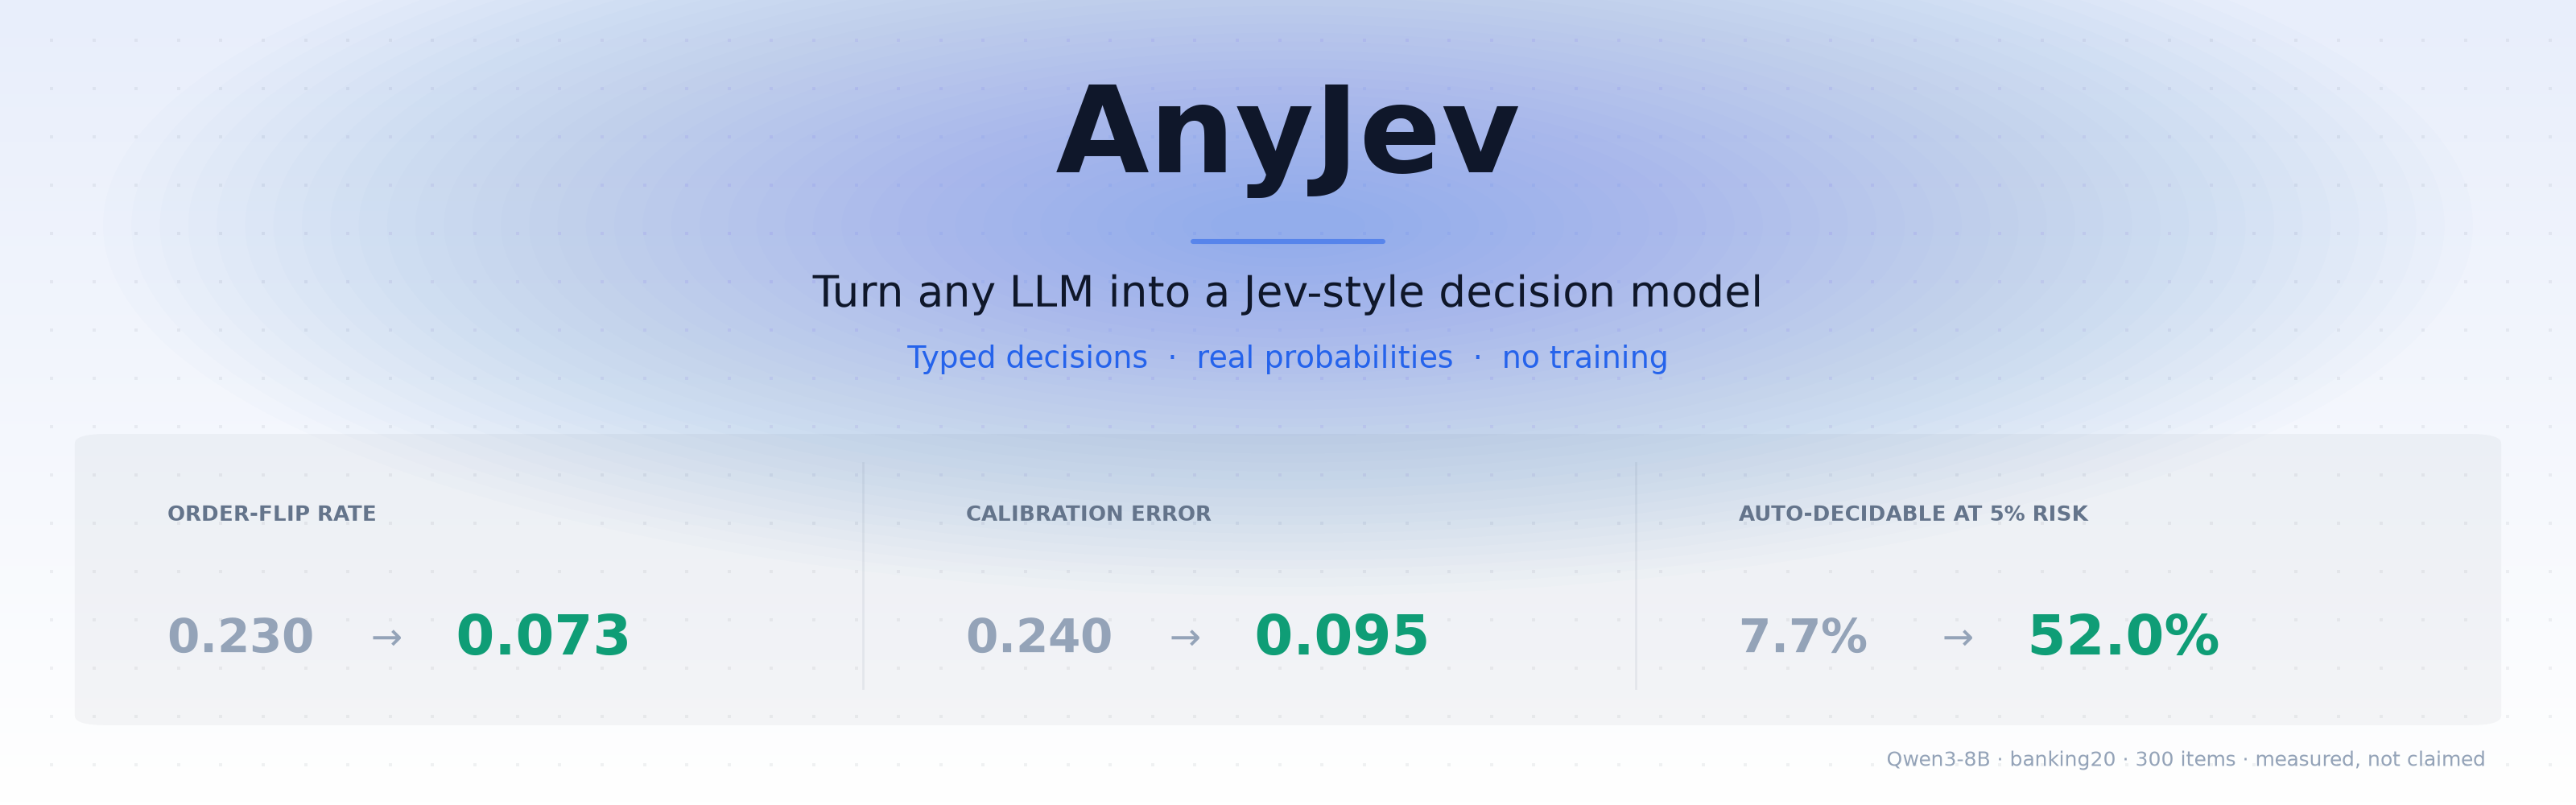
| ⚪ raw logits | 🔵 L0 zero labels |
|
|---|---|---|
| Labels required | none | none |
| Answer flips when options are reversed | 0.230 | 0.073 |
| Accuracy | 0.747 | 0.803 |
| Calibration error (ECE) | 0.240 | 0.184 |
| Auto-decidable at ≤5% error | 7.7% | 46.3% |
Qwen3-8B, BANKING77 20-way, 300 test items · bench/results_v01/2026-09-22/Qwen__Qwen3-8B.json
The last row matters most. Accuracy moves six points, but the share of decisions confident enough to automate at ≤5% error goes from 7.7% to 46.3%, with no labels at all.
| model | base | JevBench public (231) | adaptive | bev-decision test (46,320) | adaptive |
|---|---|---|---|---|---|
| Tacit-9B | Qwen3.5-9B | 0.823 | 0.887 15.2% | 0.727 | 0.755 18.1% |
| Tacit-8B | Qwen3-8B | 0.736 | — | 0.663 | — |
| Tacit-4B | Qwen3-4B | 0.723 | 0.758 14.3% | 0.663 | 0.704 17.8% |
| Tacit-2B | Qwen3.5-2B | 0.671 | — | 0.626 | — |
| Tacit-1.7B | Qwen3-1.7B | 0.619 | — | 0.598 | — |
Accuracy on every item of both sets (JevBench public
set; bev-decision test split), in the order they
are stored. First column: one forward pass per decision (adaptive=False). Adaptive: adaptive=True at
the defaults (tau=0.5, at most 20% of every 1,000 decisions), with the share of decisions sent to
reasoning in small print. Served by vllm serve (vLLM 0.17.1), run with scripts/eval_tacit.py · bench/results_tacit/2026-10-06/
On average, escalation adds 567 (JevBench) and 458 (bev-decision) generated tokens per decision for Tacit-9B, and 305 and 187 for Tacit-4B. Results with escalation for Tacit-8B, Tacit-2B and Tacit-1.7B come next.
The Decider at L0 on the unchanged google/gemma-4-31B-it:
no training, no labels, two rotations per decision. On the Decision Index 0.3 board it is
5th of 149 entries by Full score (2026-10-12).
| Full score | public 20% | same skills, private 50% | new domains, private 30% | latency median / mean / p95 |
|---|---|---|---|---|
| 60.22 | 59.79 | 59.13 | 52.98 | 98 / 260 / 1,080 ms |
The board's maintainers ran the two private parts and measured the latency (single process, one RTX PRO 6000).
Served by vllm serve --quantization fp8 (vLLM 0.29.0) with anyjev 0.3.0. Engine and run settings:
examples/decision_index (submitted as
anyjev-l0-gemma); model card:
AnyJev-L0-Gemma-4-31B ·
bench/results_decision_index/2026-10-12/anyjev-l0-gemma-4-31b.json
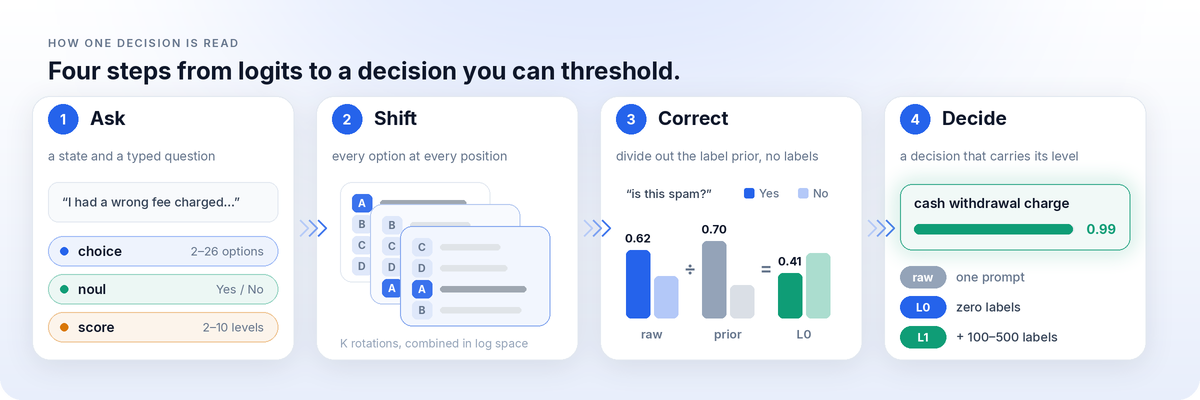
| needs | does | does not | |
|---|---|---|---|
raw |
nothing | one prompt, softmax restricted to the option labels | correct order or label bias |
L0 |
nothing | averages position bias out over the K rotations, divides out the label prior | calibrate against labels |
Tacit one_forward |
a Tacit checkpoint | one prompt, read like raw from a model trained to answer in one pass |
correct order bias |
Tacit cot |
adaptive=True |
reasons first, then reads the label distribution after the thought | run beyond its cap |
Every Decision carries its level, and require="L0" makes downstream code refuse a weaker one.
Every Tacit decision carries its route.
The contract in full →
Every number in this README is read from committed JSON. Not affiliated with TypeSafe AI or Jev.
-
choice,noulandscorefrom one prefill; L0 with zero labels - The rotation budget: L0 at about 7 of 18 rotations, with a stopping threshold certified without labels
- Tacit-1.7B, 2B, 4B, 8B and 9B on Hugging Face;
Tacitin the library on transformers, vLLM andvllm serve, with capped escalation to reasoning and an HTTP gateway - The evaluation harness (
scripts/eval_tacit.py); results with escalation for Tacit-9B and Tacit-4B - The training-free path on the public Decision Index 0.3 board (L0 on Gemma-4-31B)
- 🚧 Results with escalation for Tacit-8B, Tacit-2B and Tacit-1.7B
- 🚧 Label-free early exit: read a decision from part of the model's depth, choosing the depth by agreement with the full model
- Agent-loop evaluation: the same decisions inside a real agent
- SGLang backend (
anyjev.backends.sglang), contributed by @shentonyan - llama.cpp backend for GGUF models (
anyjev.backends.llamacpp), contributed by @Tusm11 - More log-prob backends (MLX, Ollama), span readout beyond 26 options
Dated plan and help-wanted files: ROADMAP.md. Known limitations: docs/limitations.md.
Backends are one file each, and several are help wanted (ROADMAP.md, CONTRIBUTING.md). Changes: CHANGELOG.md. Credits: CREDITS.md.
Technical Report:
@misc{zhang2026anyjevtechnicalreport,
      title={AnyJev Technical Report},
      author={Jiamu Zhang and Tianze Yang and Yucheng Shi and Evan Chen and Zixiang Nie and Kelly Wan and Liangjie Hong and Ninghao Liu and Liang Wu},
      year={2026},
      eprint={2610.00831},
      archivePrefix={arXiv},
      primaryClass={cs.LG},
      url={https://arxiv.org/abs/2610.00831},
}
Apache-2.0, see LICENSE. The Tacit models carry their base models' Apache-2.0 license. Datasets keep their own licenses, see THIRD_PARTY.md.